The Biggest Data Breaches of 2026 and What They Reveal

The biggest data breaches of 2026 have run to a pattern: fewer credit card numbers, far more health records, identity documents and account data, and at least one attack that destroyed systems rather than stealing from them. A roundup published on 15 September by TechCrunch puts the year’s incidents side by side.

Sections

The incidents by scale

Ranked by people affected, four incidents dominate the year so far.

The AI music generation platform Suno exposed information associated with 55.3 million user accounts, the largest account count of the year. Charter Communications lost more than 42 million customer records to an extortion group. The insurer DentaQuest saw health data on 15 million people stolen — the largest confirmed breach of sensitive health information in 2026. The Dutch telecoms operator Odido disclosed an attack affecting up to 6.2 million customers.

The Odido disclosure is instructive about what modern breach data looks like. Investigators found unauthorised access to a customer contact system, from which attackers downloaded varying combinations of names, addresses, email addresses, mobile numbers and personal identification details. None of that is a password. All of it is enough to open an account somewhere else in the victim’s name.

Carnival Corporation notified six million people in May that personal information had been taken in an April intrusion. Independent breach trackers, including public breach lists, record a long tail of smaller incidents behind these.

Why health data keeps topping the list

Health records have been the highest-value category for several years and 2026 has not changed that. The reason is durability. A stolen card is cancelled in a day; a diagnosis history, insurance identifier and date of birth stay valid for life and support both insurance fraud and highly credible phishing.

Healthcare and insurance environments also concentrate risk. They run large third-party ecosystems — claims processors, benefits administrators, imaging providers — each of which holds a copy of the same records. Breach numbers in the sector are frequently a count of one supplier’s customers rather than one hospital’s patients.

The attack that deleted rather than stole

The outlier of the year was at Stryker, the US medical technology company. In March, attackers described in reporting on the incident as Iranian broke in and remotely wiped tens of thousands of employee devices, disrupting the company’s operations for several days.

That attribution is as reported rather than judicially established, and should be read with that caveat. What is not in question is the shape of the attack: the objective was disruption, not extortion. Wiper incidents leave no data to negotiate over and no decryption key to buy, which makes recovery entirely a function of how well an organisation can rebuild from backups.

The most recent disclosure

The newest entry is McKesson, the pharmaceutical distributor, which discovered a cybersecurity incident on 25 August 2026 involving unauthorised access to third-party applications and data exfiltration. On 29 August the company narrowed the scope to a subset of customers within its Oncology and Multispecialty and its Medical-Surgical units.

The four-day gap between discovery and scoping is the part worth noting. Initial breach statements almost always describe a larger blast radius than the final forensic picture, or a smaller one. Early numbers should be treated as provisional in both directions.

Financial services has had its own bad month — see our report on the Revolut data breach — while the software supply chain keeps producing entry points, as our coverage of the VMware Workstation and Fusion flaw sets out.

What actually reduces exposure

For individuals, the realistic assumption is that an email address, phone number and home address are already circulating. The defences that still work are the ones that break the chain between leaked identity data and account takeover: app-based multi-factor authentication rather than SMS codes, which are vulnerable to SIM swapping; unique passwords generated and stored in a manager; and a credit freeze where the jurisdiction offers one.

For organisations, the recurring failure in this year’s list is third-party access. Suno, McKesson and DentaQuest all involve data reachable through a system that was not the company’s core product. Inventorying which suppliers hold customer data, and what each can reach, is duller than threat hunting and has prevented more incidents. Governance frameworks are catching up — our report on Microsoft’s AI code of conduct covers one vendor’s attempt to formalise those commitments.

Breach questions, answered

What is the largest known data breach of 2026?

The theft of health data belonging to 15 million people from the insurer DentaQuest is the largest confirmed breach reported so far this year.

Which incident exposed the most user accounts?

The AI music platform Suno, where information tied to 55.3 million user accounts was exposed.

What happened at Charter Communications?

An extortion group stole more than 42 million customer records, according to reporting on the incident.

What data was taken in the Odido breach?

Attackers reached a customer contact system and downloaded varying combinations of names, addresses, email addresses, mobile numbers and personal identification details for up to 6.2 million customers.

Was any 2026 attack purely destructive?

The March intrusion at the US medical technology firm Stryker was, in that attackers remotely wiped tens of thousands of employee devices and disrupted operations for several days rather than seeking a ransom for data.

What should individuals actually do?

Assume email addresses and phone numbers are already public, turn on app-based multi-factor authentication rather than SMS, use unique passwords through a manager, and freeze credit files where the jurisdiction allows it.
More on security

EU AI Act High-Risk Deadline Moves to December 2027

The EU AI Act high-risk deadline that was due to bite on 2 August 2026 has moved to 2 December 2027 for standalone systems, and to 2 August 2028 for AI built into products already governed by EU product-safety law. The shift came through Regulation (EU) 2026/1744, the Digital Omnibus package amending the AI Act, which entered into force on 27 July 2026.

On this page

What moved, and to when

The Digital Omnibus was tracked through the European Parliament as a simplification measure and published in the Official Journal on 24 July 2026. Its effect on timing is narrow but consequential.

Annex III covers standalone high-risk systems — the categories such as biometrics, critical infrastructure, education, employment, essential services, law enforcement and administration of justice. Compliance for those moves from 2 August 2026 to 2 December 2027. Annex I covers AI embedded in products already regulated under EU product-safety legislation, and that moves to 2 August 2028.

The obligations themselves are unchanged in substance: risk management, data governance, technical documentation, record-keeping, human oversight, accuracy and robustness, cybersecurity, conformity assessment, post-market monitoring and incident reporting. Only the date on which they become enforceable has moved.

What did not move

This is where several summaries have gone wrong. Three tranches stayed on their original schedule.

Article 5 prohibited practices — the outright bans, including certain biometric categorisation and social scoring — have been in force since February 2025. General-purpose AI provider obligations have applied since August 2025. And Article 50 transparency duties, including the labelling of AI-generated content and disclosure when users are interacting with an AI system, took effect on 2 August 2026 as originally written.

So a provider of a large model selling into the EU gained nothing from the omnibus. A provider of, say, a CV-screening tool gained sixteen months.

The AI Office now has teeth

The other thing that happened on 2 August 2026 is that the European AI Office’s supervision and enforcement powers became exercisable. Analyses from firms advising on the file, including Gibson Dunn, set out the scope: the Office can request information from providers, demand access to models, order mitigation measures, and require withdrawal or recall from the EU market.

Those are enforcement powers attached to obligations that are already live, chiefly the general-purpose AI and transparency provisions. The practical exposure for frontier model developers is therefore now, not December 2027.

The reason given

The justification offered for the deferral is capacity rather than policy reversal: harmonised standards under the Act were not finalised, and notified body capacity to run conformity assessments was not in place. Without a standard to build against and an assessor to certify against it, providers could not have demonstrated compliance on the original date.

Critics read the same facts differently, as evidence that the Act’s conformity architecture was over-specified relative to what European standards bodies could deliver. Both readings are consistent with the text; the Commission’s own framing is the capacity one.

The deferral also lands in a year of hardening technology policy elsewhere. Our coverage of the US chip export bills and of China’s intelligent computing plan to 2030 traces the parallel tracks.

What providers should do with the extra time

The obvious risk of a sixteen-month deferral is that teams stand down. The obligations that arrive in December 2027 are documentation-heavy and retrospective — technical files, data governance records and post-market monitoring plans are easier to build while a system is being developed than to reconstruct afterwards.

Two near-term items remain unavoidable. Transparency labelling is live now for anyone shipping generative output into the EU. And for organisations that also build or deploy general-purpose models, the AI Office’s information-gathering powers are exercisable today. Our report on Microsoft’s AI code of conduct shows how large vendors are documenting these commitments ahead of formal requirements.

What people are asking about the delay

What is the new EU AI Act high-risk deadline?

Compliance for standalone high-risk systems listed in Annex III now falls due on 2 December 2027, moved from 2 August 2026. AI embedded in products already covered by EU product-safety law has until 2 August 2028.

Which obligations were not delayed?

Article 50 transparency and AI-content labelling duties, the general-purpose AI provider obligations in force since August 2025, and the Article 5 prohibited-practices regime in force since February 2025.

What changed on 2 August 2026?

The AI Office’s supervision and enforcement powers became exercisable, alongside the transparency obligations and the penalty framework for the provisions already in force.

Why did the EU postpone the high-risk rules?

The stated reason is that harmonised standards and notified body capacity were not ready in time for providers to demonstrate conformity.

Where is this written down?

Regulation (EU) 2026/1744, the Digital Omnibus simplification package amending the AI Act, published in the Official Journal on 24 July 2026 and in force from 27 July 2026.

Does the delay apply outside the EU?

The AI Act applies to providers placing systems on the EU market regardless of where they are established, so the revised dates matter to non-EU developers selling into Europe.

Further technology coverage

Perplexity’s New AI Agent Wants to Run Your PC For You

Perplexity has brought its computer-operating AI agent to Windows. PC owners with high-end Nvidia graphics cards can now use a tool that carries out multi-step tasks, not just answers questions.

The Perplexity Windows AI agent rollout targets a specific slice of the Windows market. It requires an Nvidia GeForce RTX or RTX PRO GPU with at least 24GB of VRAM, hardware typically found in gaming and workstation PCs rather than everyday laptops.

What the agent can actually do

Rather than answering a query in a chat window, the agent operates applications on the user’s behalf. It follows instructions across multiple steps, the way a human would click through a task.

That sets it apart from Perplexity’s existing search product. It sits closer to the emerging category of ‘computer use’ AI agents that other labs have also raced to ship.

Perplexity Windows AI agent

Why the hardware requirement matters

Running an AI agent that can see and act on a screen in real time takes far more processing power than a text-based chatbot. That’s why Perplexity restricted the initial release to GPUs with substantial video memory.

That requirement limits early access to gamers, enthusiasts and professionals who already own high-end Nvidia hardware, rather than the broader Windows user base.

How this fits the wider AI agent race

Perplexity’s move follows a broader industry push toward agents that operate software directly. Several major AI labs have targeted this as the next step beyond conversational chatbots.

Apple separately opened a public beta of a rebuilt Siri, built with Google’s Gemini models, this same week. That shows how fast big tech companies are racing to ship agent-like AI features.

What happens next for the Perplexity Windows AI agent

Broader hardware support, including GPUs with less video memory, would signal that Perplexity wants to push past its current enthusiast audience.

Anyone considering the tool should weigh that it requires trusting an AI system to take real actions on their PC. That’s a step up in risk from a chatbot that only returns text.

Why Nvidia’s hardware sits at the center of this

The 24GB VRAM requirement shows how demanding these new agent tools are on graphics hardware. They often need to process screen content and run local AI models at the same time, rather than sending everything to a remote server.

That makes Nvidia’s high-end GPU lineup a gatekeeper for this new category of software. Earlier PC gaming features followed a similar pattern before becoming widely available.

Who should try it first

Owners of gaming or workstation PCs with the required Nvidia hardware are the natural early adopters. That’s especially true for anyone already comfortable granting an app broad background permissions.

Everyday laptop owners without a discrete high-end GPU will need to wait. A lighter version of the tool, if Perplexity builds one, could bring it to typical consumer hardware.

Frequently asked questions

What is Perplexity’s new Windows AI agent?

It’s an AI tool that can operate applications and carry out multi-step tasks on a Windows PC, rather than only answering questions in a chat window.

What hardware do I need to use it?

The agent currently requires an Nvidia GeForce RTX or RTX PRO graphics card with at least 24GB of VRAM, which limits it to higher-end gaming and workstation PCs.

How is this different from Perplexity’s search product?

Perplexity’s search tool answers questions using web content; this agent is designed to act on a user’s behalf inside applications, following multi-step instructions.

Are other companies building similar AI agents?

Yes. Several major AI labs and tech companies, including Apple with its rebuilt Siri, are racing to ship agents that can operate software directly rather than just chat.

Is there a risk to letting an AI agent control my PC?

Any tool that can take real actions on your computer carries more risk than a text-only chatbot, so users should understand what permissions they are granting before enabling it.

Related coverage on Tamara News

Sources

Cloudflare Just Cut Off a Whole Class of AI Bots

Cloudflare began blocking a category of AI web crawlers by default on September 15, 2026. The change could reshape how AI companies gather training and search data from millions of websites.

The Cloudflare AI crawler block targets what Cloudflare calls ‘mixed-use’ crawlers. These are bots that scrape content for both AI model training and live AI-powered search results. The new default applies to ad-supported pages across Cloudflare’s network.

What counts as a mixed-use crawler

Cloudflare draws a line between crawlers that index pages for traditional search, and those that feed scraped content into AI systems that answer questions directly, often without sending a visitor to the original site.

Mixed-use crawlers fall into the second group. They pull content for both purposes. Cloudflare argues that undercuts the traffic and ad revenue ad-supported publishers depend on.

Cloudflare AI crawler block

Why publishers have been pushing for this

News publishers have complained for more than a year that AI search summaries answer questions using scraped articles. Readers get the answer without clicking through, so publishers lose the traffic.

Cloudflare sits in front of a large share of the web’s traffic. That gives its default settings outsized influence over what AI companies can access, without individual publishers configuring blocking rules themselves.

How AI companies are likely to respond

Site owners can still opt back in and allow mixed-use crawlers. So the change works as a new default, not an outright ban.

AI companies that need continuously refreshed web content, for training and real-time answers alike, may need direct licensing deals with publishers instead of relying on open crawling.

What happens next for the Cloudflare AI crawler block

Cloudflare has rolled out similar publisher-friendly tools gradually before, watching adoption before widening scope. Other categories of crawlers could face new defaults in the months ahead.

Publishers and AI companies alike will watch whether other infrastructure providers follow Cloudflare’s lead. That would make opting out of AI scraping the norm, rather than something publishers configure themselves.

The bigger fight over who owns web content

This change is one piece of a wider dispute between AI companies and publishers. Their content trains and feeds AI models, and that fight has already produced lawsuits and licensing deals across the news industry.

Cloudflare positioning itself as a gatekeeper gives it new leverage in that negotiation. It can shift the default terms of access without any single publisher or AI company negotiating directly.

What site owners should check now

Publishers using Cloudflare should confirm their current crawler settings. Don’t assume the new default matches what you want. Sites that previously allowed all bots may now block traffic they intended to keep.

Sites that rely on AI-driven referral traffic for any part of their audience should weigh that tradeoff before deciding whether to opt back in.

Frequently asked questions

What did Cloudflare change on September 15, 2026?

Cloudflare began blocking ‘mixed-use’ AI crawlers by default on ad-supported pages across its network, a change aimed at AI bots that scrape content for both training and live search answers.

What is a mixed-use AI crawler?

It’s a bot that scrapes website content for two purposes at once: training AI models and powering AI search tools that answer user questions directly, often without driving traffic back to the source site.

Can website owners still allow these crawlers?

Yes. The new setting is a default, not a permanent block, so site owners can opt back in and allow mixed-use crawlers if they choose to.

Why does this matter for publishers?

Publishers have argued that AI search answers built from their content reduce the traffic and ad revenue their sites depend on, since readers get answers without clicking through.

Will other companies follow Cloudflare’s approach?

It’s too early to say, but Cloudflare’s scale means its default settings already influence a large share of AI companies’ ability to crawl the open web without individual publisher agreements.

Related coverage on Tamara News

Sources

Six of Every Ten Export Dollars Korea Earned in August Were Tech

If you want to know whether the AI buildout is real, look at what leaves Busan. Record
South Korea chip exports helped push the country’s technology shipments to $59.98 billion in
August 2026. The figure comes from a joint report by the Ministry of Science and ICT and the Ministry of
Trade, Industry and Energy, released on 14 September. Information and communications technology passed 60
per cent of total exports for the first time.

What South Korea chip exports actually recorded

Semiconductors did most of the work. Chip shipments rose 209 per cent year on year to $46.67 billion.
Computers and communications equipment climbed 383.1 per cent to $6.4 billion.

Total ICT exports of $59.98 billion compare with $22.84 billion in August 2025, a rise of 162.6 per cent.
The sector posted a trade surplus of $41.37 billion, also a record.

Those growth rates are extraordinary by any normal reading of trade data. They come from the ministries’
own release, and they reflect both volume and price. High-bandwidth memory used in AI accelerators carries a
far higher unit value than the commodity memory that dominated earlier cycles.

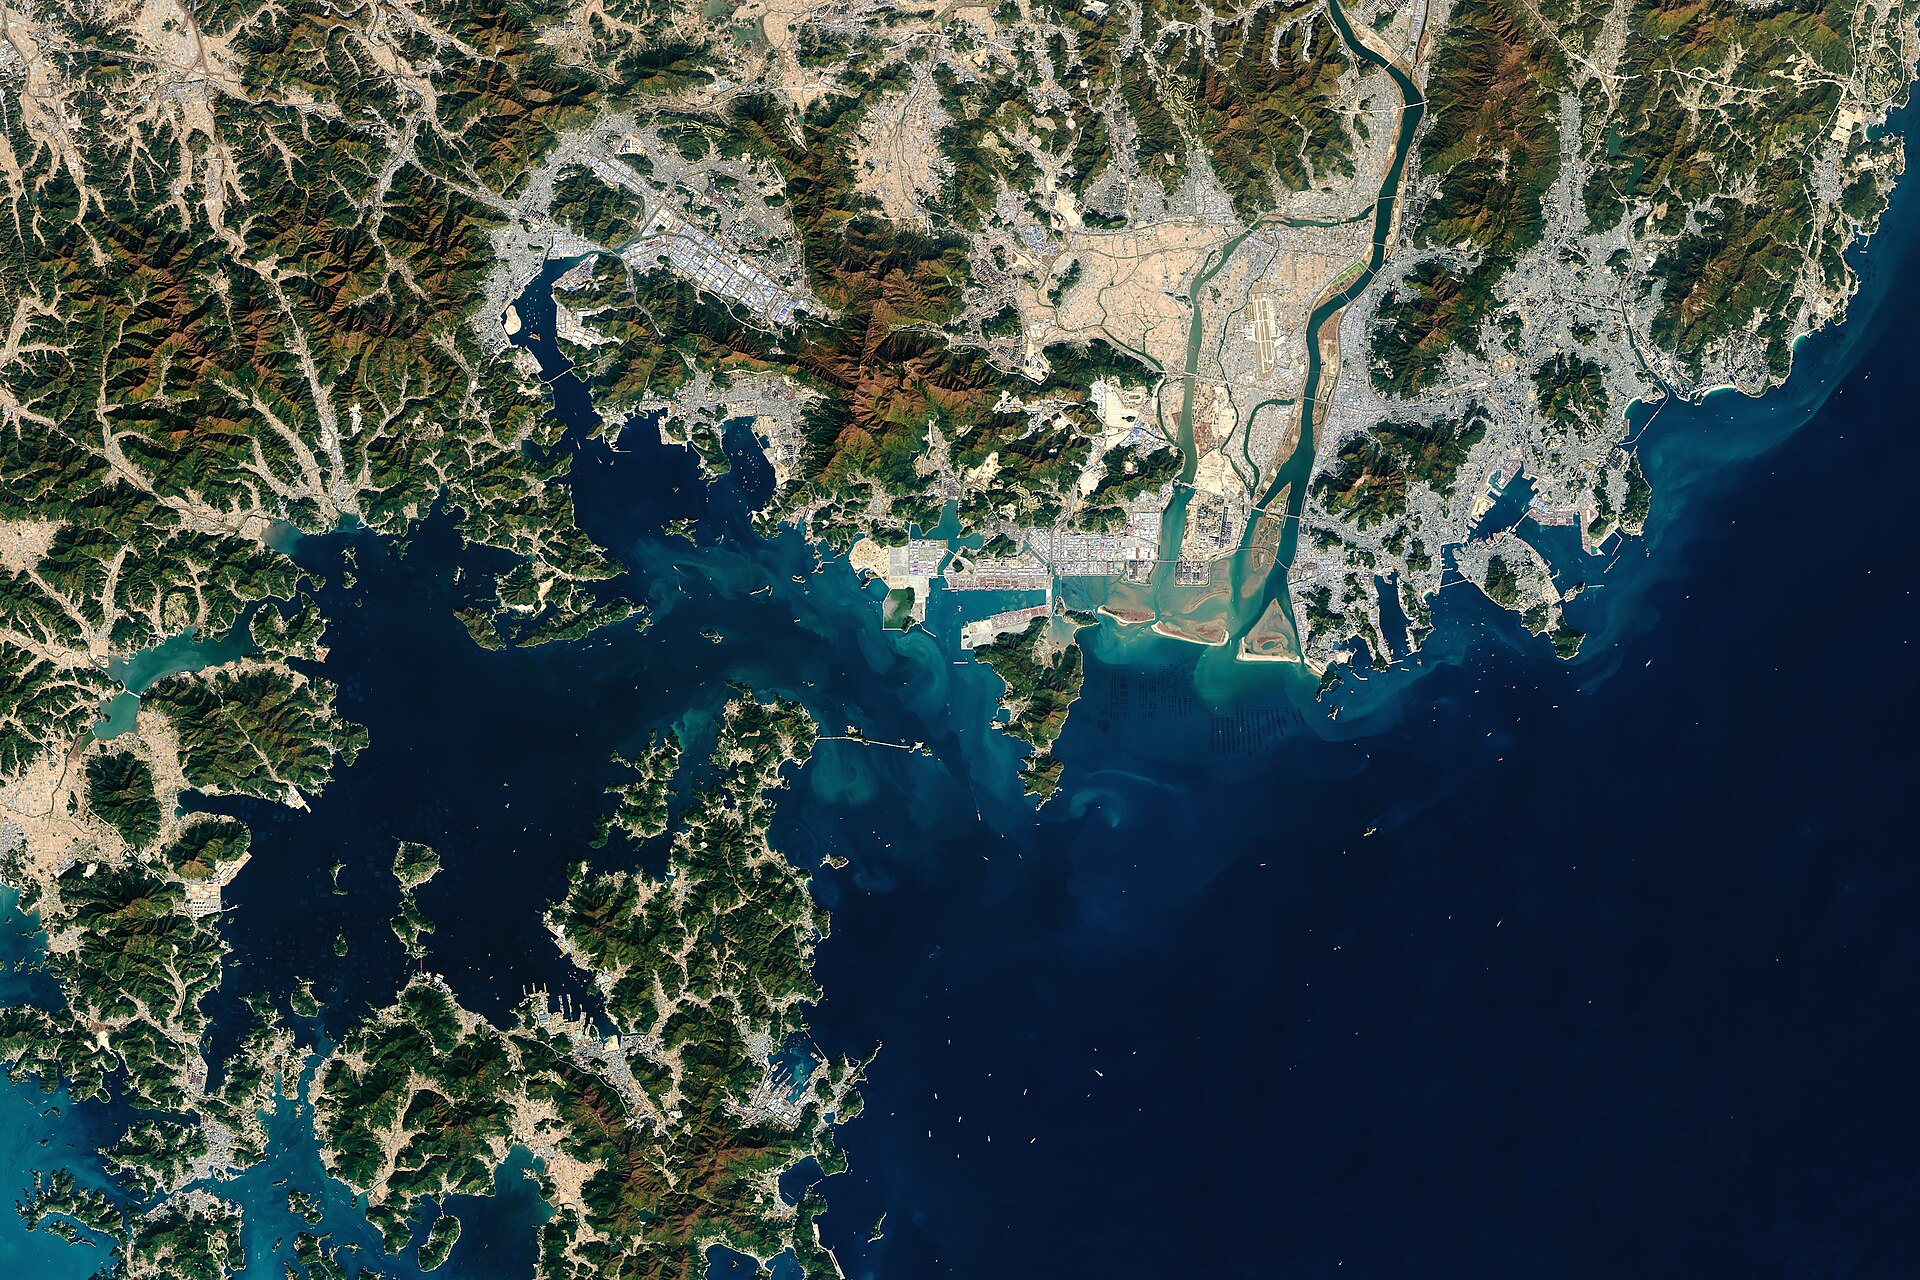
Satellite view of Busan container port, the gateway for South Korea chip exports
Busan container port from orbit. Korean memory and logic chips move through terminals like this one.

Why Korea is the cleanest read on AI demand

Samsung Electronics and SK hynix supply much of the world’s advanced memory, including the high-bandwidth
memory that AI accelerators require. Without it, a GPU cannot be assembled into a working system.

That gives Korean customs data an unusual property. It measures hardware actually shipped, not hardware
announced. Capital-expenditure plans can be revised quietly. Export tonnage cannot.

Demand spread widely by destination. Shipments to the United States rose more than 300 per cent.
Exports to China and Hong Kong, Vietnam, the European Union and India all rose sharply as well.

The breadth is the useful signal. A surge to one destination can mean a single customer stockpiling.
Growth across the United States, China, Vietnam, Europe and India at once points to broad build-out rather
than one buyer’s inventory decision.

Vietnam deserves a note of its own. Much of what ships there goes for assembly and test before moving on
again. Its numbers partly measure the same demand a second time, further along the chain.

The concentration underneath the record

A sector at more than 60 per cent of national exports is a strength and an exposure at the same time.
Reporting on the release noted that stripping ICT out would leave the country running a trade deficit of
about $6.6 billion for the month.

That is the risk in one number. Korea’s external accounts now depend heavily on one demand cycle in one
industry.

The timing sharpens it. These figures landed the same week AI lab chiefs called publicly for slower
frontier-model development, and chip stocks fell across three continents. Our reports on
that slowdown call and
on the Qualcomm-Amazon AI chip
deal
cover the demand side of the same market. Korea’s own policy response runs through skilled
migration too, as our piece on
China’s competing
computing plan
shows for the region.

What the record changes for the rest of the market

For buyers, sustained Korean output eases the memory shortage that has constrained accelerator supply.
For competitors, it raises the bar: matching this volume takes fabs that take years to build.

For policymakers elsewhere, the data is an argument in ongoing subsidy debates. Countries funding
domestic semiconductor capacity will cite these figures in both directions — as proof the market is worth
entering, and as proof of how far ahead the incumbents already are.

Whether the numbers hold

Three things decide that. The first is whether AI capital spending continues at its current pace into
2027. The second is memory pricing, which has driven much of the value growth and can fall quickly. The
third is export-control policy, which shapes where Korean fabs can sell and what equipment they can buy.

September data, due in mid-October, is the next check. A single record month proves a peak. Two
consecutive ones start to prove a trend.

Export data questions

How large were the exports?

ICT exports reached $59.98 billion in August 2026, up 162.6 per cent from $22.84 billion a year earlier.

How much of that was semiconductors?

Chip exports were $46.67 billion, a rise of 209 per cent year on year.

Who published the figures?

The Ministry of Science and ICT with the Ministry of Trade, Industry and Energy, in a report released on 14 September 2026.

What share of total exports is ICT now?

More than 60 per cent, the first time the sector has passed that threshold.

Why do these figures matter for AI?

Samsung and SK hynix supply much of the high-bandwidth memory AI accelerators need, so Korean shipments track real hardware demand.

What is the risk in the record?

Concentration. Reporting on the release noted that without ICT, Korea would have run a monthly trade deficit of about $6.6 billion.

Citations